Chapter 20. Generic Software
This chapter converts the derivation into economics. A one-line corollary collapses every domain application into one generic engine specialized by data; the browser and the spreadsheet are the existence proofs. Two consequences follow: domain functionality ships as data, and computation stays outside the engine, submitting its results through write like any other caller. The chapter closes on the incentives that keep bespoke code in place despite them.
Specialized by data
Start from a corollary the apparatus yields at once:
Prop. 20.1. Two proper applications over (5.3) differ only in their terms and their state.
Proof — S2 plus Theorem 5.4 leave nothing else to vary.
By S2, each factor is the denotation of a term; by Theorem 5.4, the state model is shared. What remains to vary is (q, t, s) and the facts. ∎
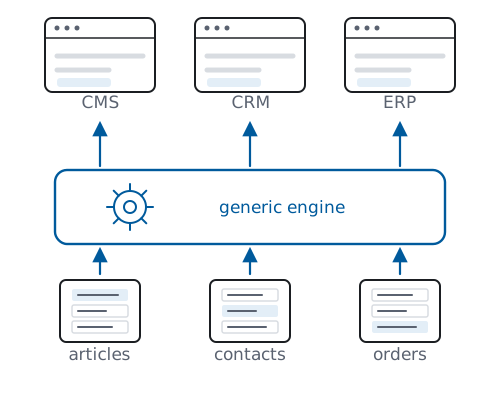
It follows that the difference between a CMS, a CRM, and an ERP is data. Each is a UI layer around CRUD over a domain model. The domain model is facts (5.3), and the UI is ⟦t⟧ and ⟦s⟧. CRUD is read and write, Definition 1.1 and Prop. 7.1, which HTTP already implements. One application can serve every domain, specialized by data rather than by code.
Two proofs and a failure
The web has already run this experiment once, and the result is so familiar it goes unnoticed as an example: the browser. One client for every website. Nobody writes a per-site browser, and nobody marvels at that, which measures how completely the uniform interface won at the document layer. Chapter 4 typed the four clauses that won it, and generic software is their result, built layer by layer: generic caches, generic crawlers, one generic renderer. That generic software reached only as far as the interface was uniform. Behind every GET the verbs are shared and the state is bespoke, so the client that is generic in transfer stays bespoke in understanding. That means one adapter per API, and Chapter 23 totals the arithmetic. This chapter asks why the browser, generic over documents, never got a counterpart generic over state, and the answer is that nothing was missing except the state model Chapter 5 derived.
The claim has a second existence proof, older than the web. The spreadsheet is the most successful generic application in history: one engine serves every domain, specialized by nothing but its data. No vendor ships an accounting spreadsheet and a separate logistics spreadsheet; users pour the domain in as rows and formulas. The spreadsheet’s own limits explain why it could prove no more: cell references are sheet-local (R3), two workbooks have no merge (R2), and the world’s operational data lives in a million silos named final_v2.xlsx. The derived stack is the same generic engine, but with names that cross files and states that compose. Each proof carries half the claim: the browser is generic with the web’s properties, at the document level; the spreadsheet is generic over domains, with none of the web’s properties. This chapter describes an application that holds both halves at once, and it was sitting in the standards all along.
The idea has also failed before, and the failure shows exactly what to avoid. Model-driven architecture (MDA) promised applications generated from models, and broke on its own compiler. The model was translated into code, the code drifted from the model, and the model ended up as documentation only, because that first generation step severed S2. The generic engine makes no such translation. The ontology is never compiled into the application; it is the application’s data, interpreted at runtime like everything else, so nothing drifts because nothing is copied.
A codebase is a liability
The economics follow. A codebase is a liability, not an asset: behavior held equal, the number of bugs is roughly proportional to the number of lines. So a system is better when it achieves equal behavior with less code, and the generic system achieves it with no domain code at all. Domain functionality becomes a declarative package: an ontology and a stylesheet pair, imported into a running application. Installation is not a deployment but a merge: the package is data, so adding it is a union, and removing it is a delta — it uninstalls the way it installed. And the pair carries its own correctness check. By B.8’s relativization result, the stylesheet may treat specially only the names the ontology and its imports declare: what it touches stays inside the declared vocabulary, checkable from the term alone. So a package either declares the vocabulary it renders, or the check finds the undeclared names it renders. Chapter 12 audited the binary-delivery web; this is its constructive alternative: behavior defined by data, shipped as data, revocable as data.
The reference implementation ships exactly this: applications as importable datasets, administered by an application defined in the same terms it administers. Chapter 19’s exhibit rebuilds a newspaper and a dashboard on one machine. This chapter’s claim is that the rebuild generalizes: the two reconstructions are datasets for the same generic engine, and the book’s online edition is a third.
In the world. Enterprise architecture reached this chapter’s conclusion from the cost side, without deriving it. Dave McComb’s Software Wasteland (2018) is a book-length audit of the application-centric mindset, every enterprise rebuilding the same CRUD over its own bespoke model. Its sequel The Data-Centric Revolution (2019) prescribes the data-centric cure this chapter derives: make the data the fixed point and let one generic substrate be specialized by an evolving model, not by code. Those books argue it from decades of enterprise waste; Proposition 20.1 states the same result as a corollary.
In the world, dated 2017. The liability has a mainstream witness. James Somers’s Atlantic essay “The Coming Software Apocalypse” surveys the damage done by software that has grown too large to understand. A statewide 911 outage was traced to one counter’s threshold. Eighteen months of expert review barely untangled the throttle code of a runaway Toyota. A car now carries a hundred million lines. Unmoored from anything physical, software “tends to grow without bound”, into systems, as Nancy Leveson writes, “beyond our ability to intellectually manage.” One interviewee states this chapter’s remedy: “Nobody would build a car by hand.” The essay also records the wall those remedies hit: engineers recoil from the word “formal,” and an Amazon engineer won colleagues over only by retitling formal specification “debugging designs.” The tools were sound and the resistance was to their image — the same failure this book calls abandonment, not refutation.
Computation on the write side
One objection lands here with real force, and it deserves the treatment latency got in Chapter 7: real domains compute. A payroll run turns timesheets into pay; an allocation turns orders into reservations; an invoice’s total is computed, not typed in. If the engine houses no domain code, who computes? Definition 1.1 answered before the question arose: it types what the application is (read and write) and says nothing about who calls it. Chapter 7’s caller was a human holding a form. A computation is another caller: an agent that reads, computes, and submits its conclusion through the same write, in the same normal form, reviewable and invertible like every delta. Chapter 23 shows what that reviewability does for governance.
Much of what domains call computation is derivation: producing facts that already follow from the facts held — the invoice’s total from its lines. The derivation step needs no new language either. Prop. 7.3 turned a pattern plus bindings into a delta, with the bindings supplied by a form; draw the bindings from the state instead and you have a rule: match what holds, assert what follows. SPARQL Update ships exactly this construction, an INSERT whose delta is computed by its own WHERE clause — the same algebra as the form, with the state supplying the bindings a human would have typed.
What lacks a recommendation is when such a term runs — schedule, trigger, threshold. That is the orchestration seam, open like identity and access in Chapter 19, and like them awaiting convention rather than invention.
So the domain’s logic divides cleanly. Validation is a predicate on deltas (Chapter 7 drew that line). Derivation is an update term over the ontology. That places inference precisely: an entailed fact enters by that write, not by a closure computed at read time, so the state remains the asserted set. And whatever imperative computation remains (the solver, the optimizer, Chapter 12’s leaf) runs behind a caller, submitting deltas like everyone else: outside the engine, never inside it.
The incentives
Why, then, does every domain still get its own codebase? Chapter 13 supplied the mental models; the incentives supply the motive. Generic software commoditizes its vendor: a domain application’s defense is precisely its bespoke code; the industry charges rent on that code and will not embrace generic software, which dissolves the asset. So the push has to come from consumers, and Chapter 23 names them: human users never noticed the cost of bespoke code, but an agent needs a bespoke adapter for every application it touches.