Chapter 19. No New Standard
Chapter 18’s build log ran on deployed standards end to end, and this chapter shows that nothing more is needed. Three questions remain: how names relate to addresses, how the seams that lack Recommendations get filled, and what shape federation forces on a reference implementation. Each resolves by composing pieces that already ship. No new standard is proposed. The chapter closes with the existence proof: an implementation that runs Chapter 18’s assembly.
Names and addresses
The first GET raises the first question. It is the web’s oldest identity crisis, filed at the TAG (the W3C Technical Architecture Group) as httpRange-14: what does dereferencing the name of a thing return, when the thing is a turbine rather than a page? A decade of W3C argument produced a 303-or-fragment resolution, a note (Cool URIs for the Semantic Web), a reopening, and a deployed practice that largely ignores all of it.
The model here has a shorter account. Names and addresses are different roles, typed apart since Chapters 4 and 5: a URI in a fact position names (R3); a URI addressing a projection locates (S4). So the question is settled by computation, not argument. Dereferencing a name returns read(name, S), a description of the named entity. Its address may coincide with the name, differ by a fragment, or differ by a redirect; the choice among the three is a wire-level detail, and nothing in the architecture depends on it. Only the collision is real. Use one URI as both name and address, and the entity is conflated with the document that describes it: “the turbine weighs 200 tons” and “the description was modified on Tuesday” now share a subject. That conflation is a data-discipline cost (measurable, like Chapter 9’s mismatches), and keeping name and address apart, by fragment or by redirect, avoids it.
The exhibits already resolved the question both ways. The Guardian’s articles collapse the two harmlessly (an article is its own description) while the wind farm’s panels sit one hash away as fragments (#panel-14). That fragment is the convention the reference implementation adopts: one GET serves entity and description alike. So the crisis reduces to a typing discipline the model already draws, plus an encoding choice the deployment already made.
Composition, not creation
Three seams lack Recommendations: identity, access control, and the form-native write. The first two have candidates with running code, and both fill their seam with the model itself. WebID has been incubated at the W3C since 2005 and never advanced to Recommendation. It makes an identity a URI whose dereference is a profile: an agent is an entity, its identity a graph, authentication a proof that the keyholder and the profile agree. WebAccessControl is an ontology grown on the W3C wiki, since adopted by Solid, Berners-Lee’s re-decentralization project. It states permissions as facts (who, which mode, over what) so an ACL is data in the same state model it guards. Identity and authorization collapse into the substrate they protect (previewing Chapter 20’s thesis) and the reference implementation below runs both. For the third seam, Chapter 9’s bridge (RDF/POST) slots a plain HTML form into the write side. RDF/POST is specified, not standardized. And as Chapter 9 showed, it is an encoding rather than an invention: it adds neither a model nor a protocol.
This part has contained no proposal for a new standard, and that absence is the finding. Part III showed the read side complete by 2014. The write side’s last mile is an encoding of what already ships. The remaining seams have candidates that compose deployed pieces. Nothing here waits on a working group. The community’s long reflex (meeting every gap with a new specification) aims at the wrong layer. After the reveal, the remaining work was never specification. It was combination: an implementation that assembles the standards in the derived shape.
The reflex has a Recommendation-grade instance: the Linked Data Platform (LDP, 2015), which claimed this book’s exact slot (a read-write Linked Data architecture) at the interaction layer. The Graph Store Protocol (HTTP’s methods addressed to whole graphs) was already standardized. LDP’s one addition to it is the container, a server-side collection with protocol-managed membership. But a container is a canned selection, a query frozen into the interface. It came after SPARQL had already made every collection open-ended: any members, by any pattern, composed at request time. Subtract the containers and nothing remains that the Graph Store Protocol does not already do: LDP added interface where query semantics sufficed. The gap was in the implementations, which never combined what the protocols already offered.
The chapter’s exhibit mirrors Chapter 3’s, deliberately: the two stripped sites are rebuilt as dataspaces. The strip-2 fact lists are loaded as state, with a small ontology per domain: articles and sections for one, panels and readings for the other. Each dataspace gets one select term per window, an arrange term per layout, and a stylesheet per look. Front page and dashboard become two declarative packages over the same generic machine; both domains live entirely in data. Chapter 3 computed the factorization by hand; this chapter runs it forward, on the same material. Analysis and synthesis meet on worked examples. (The full-scale reconstruction is being built in public, as Chapter 3’s exhibit once was; the miniature below runs today.)
StateState — the domain lives herepanel-14 type Panel panel-14 title "Current Power" panel-14 value "15.5 kW" panel-14 partOf overview panel-7 type Panel panel-7 title "Wind Speed" panel-7 value "8.2 m/s" panel-7 partOf overview panel-3 type Panel panel-3 title "Grid Frequency" panel-3 value "49.98 Hz" panel-3 partOf archive farm name "Anholt Offshore"
select — the window?p partOf overview ?p title ?t ?p value ?v
canon(Data) — the canonical serialization@prefix d: <https://wind.example/farm#> . @prefix w: <https://wind.example/vocab#> . d:panel-14 w:partOf d:overview ; w:title "Current Power" ; w:value "15.5 kW" . d:panel-7 w:partOf d:overview ; w:title "Wind Speed" ; w:value "8.2 m/s" .
arrange — the term t: t₁ · cardspresent — the stylesheet: consoleread(r, S) — the documentCurrent Power
- partOf
- overview
- value
- 15.5 kW
Wind Speed
- partOf
- overview
- value
- 8.2 m/s
Interactive exhibit (online edition): the reconstruction in miniature. The two datasets from Chapter 3 under one generic engine — swap the data, the selection, the arrangement, or the stylesheet, and the factors you did not touch hold still. The full-scale reconstruction runs the deployed standards (SPARQL, XSLT, CSS); this miniature runs the book’s own algebra.
The federation test
Federation needs a client, and the derivation says so before any implementation does. R3 put foreign names inside local facts. In deployment, following one means calling another party’s read. A window over another party’s state is ⟦q⟧ posed to another party’s endpoint. Consuming dataspaces is therefore the other half of the architecture, not a feature an application adds. A dataspace that only serves is a leaf, because it never follows anyone else’s names. So a reference implementation has a forced shape, both halves at once: a server publishing (18.1)’s four components (origin, ontology, endpoint, stylesheet) and a client consuming the same four from any other dataspace.
Both halves in one implementation enable a test no bespoke system can run: point the implementation at itself. Two instances run at two origins, and one of them browses, queries, and writes against the other. Every capability crosses the wire or fails visibly, because no in-process shortcut exists for a demo to lean on. Self-federation is the architecture’s own strategy put under test: two instances meet as strangers, and the first federation is its own. And the test is not circular. S2 leaves the two instances nothing private to share. Everything that crosses the wire is a term of a closed language (data, query, delta, arrangement), so they meet only on the specifications’ surface, with no side channel to agree over. The standards process proves interoperability with two independent implementations. A reference implementation proves it with two instances of itself. That evidence is weaker, but it is available years earlier, and it holds only as long as the wire carries nothing but spec-terms. A second implementation joins by implementing the same denotations, over the same interface the self-federation test already exercised.
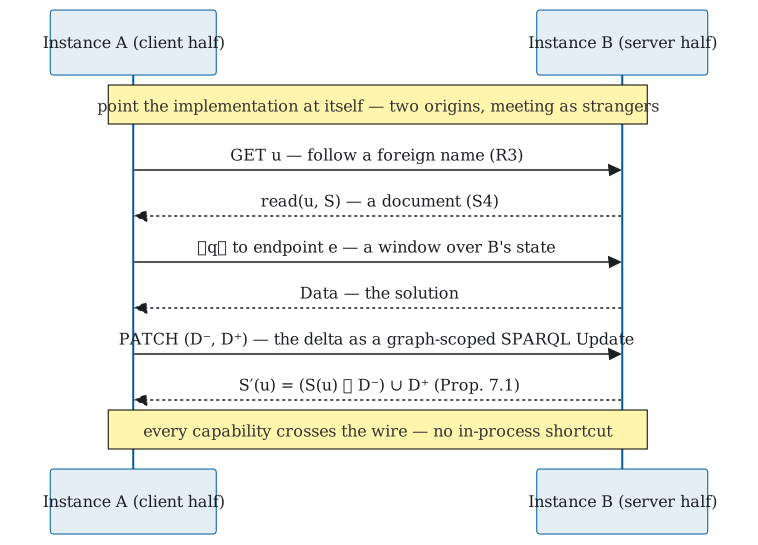
The federation test, drawn. Each instance runs both halves. Here Instance A’s client consumes Instance B’s server across three exchanges. It dereferences a foreign name (R3) for a document (S4). It poses ⟦q⟧ to the endpoint e for a window. It submits a delta (Prop. 7.1) as a PATCH, a graph-scoped SPARQL Update. Because S2 leaves nothing private, the meeting surface is the specifications’ surface alone.
The document web bootstrapped exactly this way. The pattern, stated generally: a server and client pair whose self-interoperability is the first running instance of a protocol anyone may join.
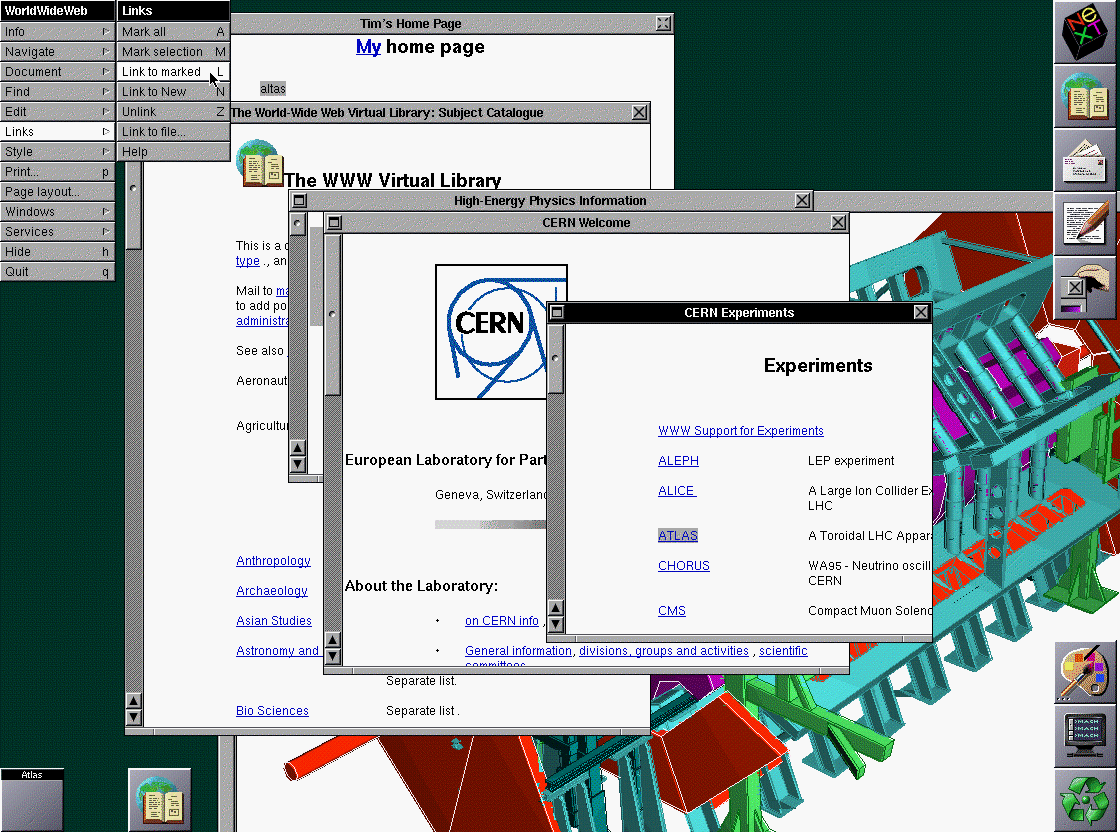
The first instance, dated. This is not an analogy; it happened. In 1990 the first web server (info.cern.ch) and the first browser ran on two NeXT machines at CERN and interoperated with each other before there was a third program in the world to interoperate with. That browser (WorldWideWeb, soon renamed Nexus so the web could keep the name) was also an editor: reading and writing went through one program. The write side was there on day one, then lost for a generation as the read-only browser became the thing everyone shipped. The federation test above makes that first day a permanent requirement.
The existence proof
This chapter is where the book’s existence proof enters as evidence. The architecture has a reference implementation: LinkedDataHub, open source, in production for years. It federates the way the section above requires: instance to instance, its client half consuming what its server half serves. It also delivers the chapter’s other promises: WebID and WebAccessControl are running, RDF/POST is accepted on the write side, and an entity’s name differs from its description’s address by only a fragment. And the online edition of this book is being built on it, keeping the promise the preface made. The point of an installable existence proof is that no one has to take the book’s word for it.